How to evaluate AI summaries, lead scores, writing assistants, and automated actions without treating model output as verified customer truth. This guide is written for a sales executive considering AI-assisted prospecting and support summaries for a mid-sized company. It explains the tradeoffs a buyer can check without treating sales claims, product popularity, or advertising promises as independent evidence.
Before adding another subscription, identify the decisions, records, and people affected by the proposed software change. For this subject, the central decision is specific: Start with bounded tasks and accountable human decisions before allowing AI to write back to production records. The examples below are illustrative exercises, not claims that any named supplier has failed or passed an audit. Features, prices, data processing terms, and plan availability can change; verify the actual service before purchasing.
Begin with a decision the organization can defend
Consider the following representative situation: A sales executive considering AI-assisted prospecting and support summaries for a mid-sized company. A selection meeting will be more useful if it establishes owners, measurable acceptance criteria, and the information the chosen service must protect. A product demonstration is a starting point for asking better questions; it should not replace a documented trial, a contract review, or a defined recovery route.
Start with bounded tasks and accountable human decisions before allowing AI to write back to production records. Put this sentence at the top of the evaluation worksheet and ask each stakeholder to state which evidence would change their recommendation. That exercise prevents a conversation about attractive features from displacing practical questions about data handling, team adoption, business continuity, and responsibilities after launch.
Eight issues to evaluate in depth
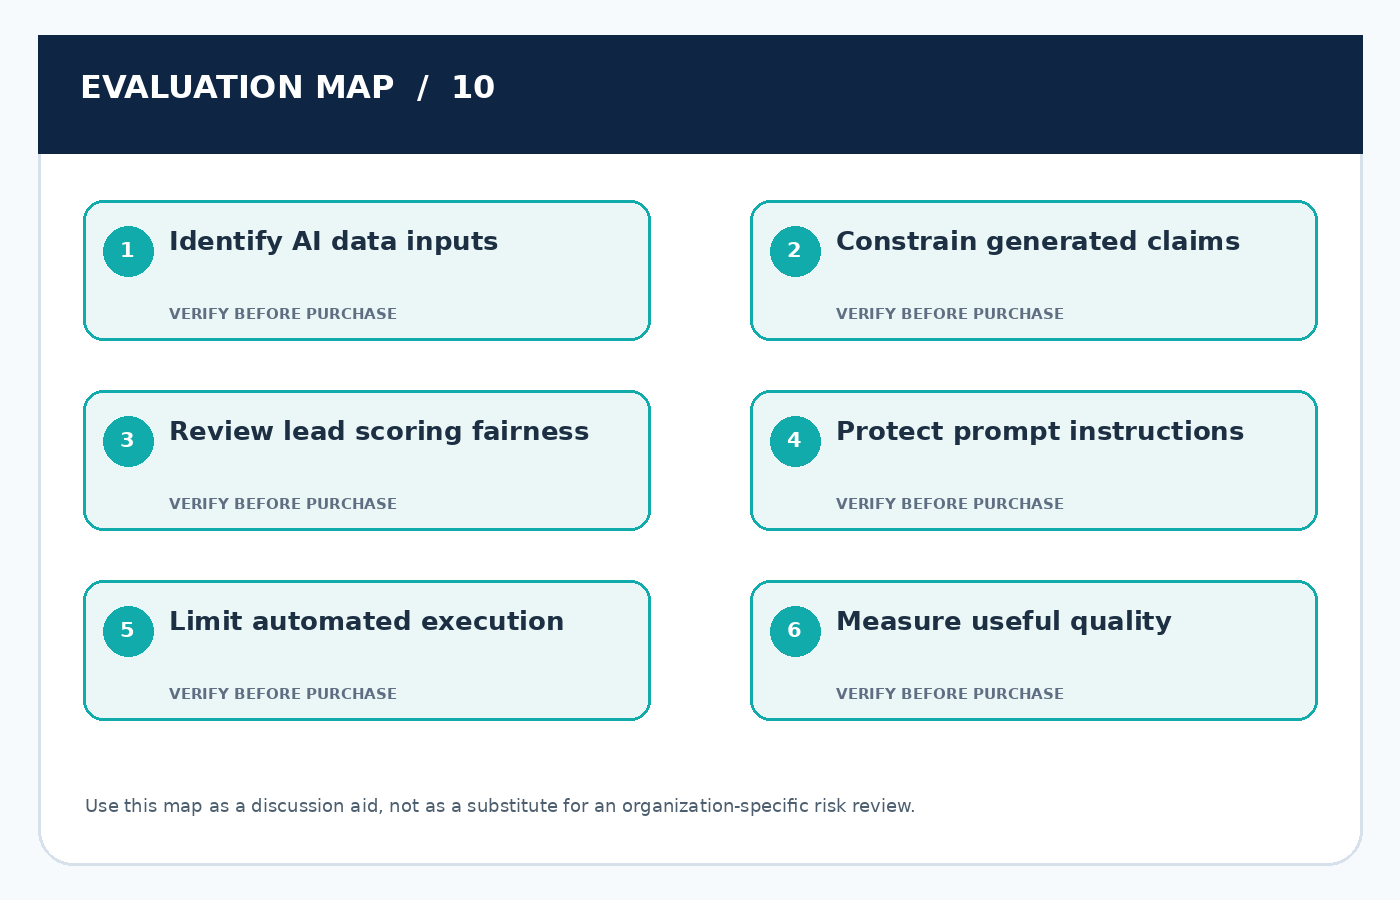
1. Identify AI data inputs
Determine whether models see complete notes, recorded calls, customer attachments, account relationships, and data supplied through third-party integrations.
Failure to anticipate: A summarization feature can move sensitive sales or customer information outside the original processing path even when the interface looks like part of the CRM.
Evidence to request: Request a data-flow diagram, processing terms, retention settings, feature-level controls, and evidence of what a typical prompt includes.
2. Constrain generated claims
An assistant can draft plausible yet false next steps, meeting details, prices, or account histories that were not present in the approved source material.
Failure to anticipate: Automatically saving an invented promise as an agreed customer commitment can create operational and reputational problems even without an external security incident.
Evidence to request: Test with fabricated records containing deliberate ambiguity, demand citations or source links where supported, and require human confirmation for consequential updates.
3. Review lead scoring fairness
Scores can reflect historical selection bias, missing information, seasonal behavior, and choices made by earlier sales teams.
Failure to anticipate: A high score may receive preferential attention because the training data mirrors past prioritization rather than current customer suitability.
Evidence to request: Ask who owns the outcome definition, compare segments, document override procedures, and monitor whether score explanations support reasonable business decisions.
4. Protect prompt instructions
Email bodies, attachments, websites, and imported notes may contain text designed to redirect AI behavior away from the user's approved objective.
Failure to anticipate: A malicious customer note can appear as a command to the model and attempt to disclose context or change a workflow if tool permissions are too broad.
Evidence to request: Treat external text as untrusted data, restrict tool access, test adversarial samples, and prevent a model from independently performing privileged actions.
5. Limit automated execution
Writing assistance, opportunity summaries, email sending, and record deletion represent increasingly different risk levels and should not share the same approval policy.
Failure to anticipate: A workflow that begins as suggested text may later acquire permissions to trigger customer communications without anyone revisiting its governance.
Evidence to request: Classify actions by impact, use preview and confirmation for external effects, retain an intervention mechanism, and log who approved final execution.
6. Measure useful quality
A feature that feels impressive in a demonstration should be judged on measurable changes to representative tasks and known failure patterns.
Failure to anticipate: Counting generated summaries may conceal inaccurate extraction, higher review time, or staff abandoning outputs because confidence is low.
Evidence to request: Build a small evaluation set, define precision and usefulness criteria, log corrections, and track whether task completion improves after review time is included.
7. Check vendor controls
Features may be enabled by default, use different retention terms, or become available only in enterprise editions with distinct administrative options.
Failure to anticipate: General assurances about the core CRM may not apply to an externally hosted assistant or optional voice-transcription service.
Evidence to request: Obtain feature-specific documentation, validate tenant controls, verify supported disablement, and establish a review when model or processing terms materially change.
8. Plan a bounded launch
Teams often adopt AI fastest when given a narrowly described job, examples of unacceptable outputs, and a clear route to flag mistakes.
Failure to anticipate: A broad mandate to use AI everywhere can cause sensitive data to be shared through unapproved tools and discourage staff from reporting errors.
Evidence to request: Pilot a single internal summarization workflow with synthetic or appropriately approved data, measure corrections, then expand only with a named owner.
Procurement questions worth writing down
These questions translate the operational discussion into a decision record. Do not send them as an unexplained survey; ask the supplier to demonstrate answers in the actual subscription tier and have the business owner confirm the evidence.
- Identify AI data inputs: Can the proposed capability be demonstrated with a fictional but realistic operating example rather than an idealized vendor dataset?
- Constrain generated claims: Who approves an exception, which evidence is retained, and what event triggers a review or revocation?
- Review lead scoring fairness: What additional edition, storage, implementation, or integration cost is required to make the promised capability operational?
- Protect prompt instructions: How would an employee notice that the control failed, and who is accountable for containment and correction?
- Limit automated execution: Can the organization retrieve the relevant information and relationships in a usable format if it changes supplier?
- Measure useful quality: Which feature depends on another product or subprocessor, and how will material changes be communicated to the customer?
- Check vendor controls: What task would staff complete during a vendor outage or a permission-related lockout?
- Plan a bounded launch: Which exact records, identities, or business events are within this requirement, and what is deliberately out of scope?
A realistic 90-day adoption plan
First 30 days: constrain generated claims
Create a simple register of customer record types, participants, and connected tools. Agree on a constrained example that represents ordinary work and a realistic exception. Review contractual boundaries and existing identity settings before trial data enters any external service. The focused activity in this phase concerns constrain generated claims; use an approved test record and retain the outcome for the rollout decision.
The checkpoint should include the decision owner, a clear pass-or-fail observation, and an agreed route to fix any unresolved issue. A planned launch date alone is not an acceptance criterion.
Days 31–60: limit automated execution
Run permission, workflow, and data-flow tests using synthetic records. Capture screenshots or exportable audit evidence where permitted. Assign each finding to a named owner, separate blockers from improvements, and revise the proposed operating process rather than relying on informal fixes. The focused activity in this phase concerns limit automated execution; use an approved test record and retain the outcome for the rollout decision.
The checkpoint should include the decision owner, a clear pass-or-fail observation, and an agreed route to fix any unresolved issue. A planned launch date alone is not an acceptance criterion.
Days 61–90: plan a bounded launch
Complete acceptance testing with actual job roles, rehearse a revocation or restore scenario, and establish the first access and vendor-review date. Keep a small decision log that records what was checked, which limitations remain, and why the selected workflow meets the organization’s requirements. The focused activity in this phase concerns plan a bounded launch; use an approved test record and retain the outcome for the rollout decision.
The checkpoint should include the decision owner, a clear pass-or-fail observation, and an agreed route to fix any unresolved issue. A planned launch date alone is not an acceptance criterion.
Frequently asked buyer questions
What should we validate before paying for a solution related to identify ai data inputs?
Test a small, representative process with fictional records and obtain a written explanation of the service boundaries. The aim is to understand the exact purchased capability, the conditions under which it works, and whether it can be monitored by the customer after launch.
Which hidden risk tends to be overlooked in review lead scoring fairness?
The most common evaluation gap is treating the expected operating path as the only possible outcome. Include a negative test, agree on what a failure looks like, and name the individual who will investigate the exception rather than letting a supplier treat it as an edge case.
How can a small team conduct a meaningful trial without a large budget?
Concentrate on one workflow, a limited set of synthetic records, and staff who perform the job. A short, documented trial often produces better evidence than an extensive feature tour with no agreed success criteria. Protect sample information and document what would justify purchasing the next tier.
When should we reconsider the original buying decision?
Reopen the evaluation when the service boundary, pricing, team structure, data sensitivity, or business process changes significantly. Good stewardship is ongoing: the original procurement decision is not permanent authorization for every later use. Reassess unresolved risks and test that transition rights still work.
Official resources and further reading
These sources provide background principles and guidance. They do not endorse the fictional scenarios or certify a vendor mentioned in this article.
- NIST AI Risk Management Framework
- NIST CSF 2.0 Small Business Quick-Start Guide
- FTC Cybersecurity for Small Business
Editorial conclusion
The right answer depends on workload, the value and sensitivity of the records, internal capacity, and the precise service terms. For ai features in crm: security, accuracy, and human oversight, a defensible decision follows from the checks above and from an honest discussion of what cannot yet be demonstrated. Make unresolved questions visible, preserve a practical exit path, and recheck assumptions after the system becomes part of day-to-day work.
Related Posts
CRM Vendor Security Due Diligence: Questions Procurement Should Actually Ask
A purchase-ready evidence list that distinguishes meaningful assurance from attractive…
CRM Privacy by Design: Consent, Retention, and Data Minimization
A practical way to govern customer information across lead capture,…
CRM Backup and Disaster Recovery: Testing Business Continuity
How to define recoverable CRM operations, validate exports, and avoid…